Bring conversations together
Reducers read snapshots, never APIs. Every source publishes the same thing: a schema, record IDs, provenance and a version. Refresh is a new snapshot.
· 3 min read · Updated October 7, 2026
Key ideas
- Reducers read snapshots, never APIs.
- Every source publishes the same thing: schema, record IDs, provenance, a version.
- Refresh is a new snapshot. Old runs keep theirs.
A reducer never calls Pylon. It reads a snapshot that a Pylon connector published. That one boundary is what lets the same question run over support tickets on Monday and call transcripts on Tuesday without touching the workflow.
One contract for every source
Import records
Raw evidence
Structured fields
Source references
Check the contract
Schema
Coverage
Provenance
Versioned snapshots
Run A → snapshot 1
Run B → snapshot 2
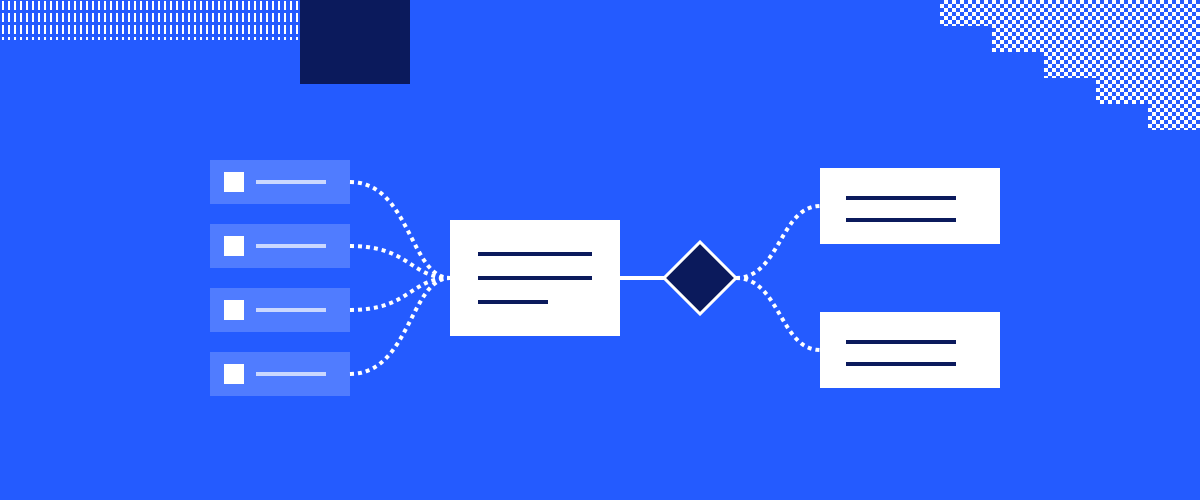
Every adapter, a connector or a file parser, emits the same things: raw evidence, candidate structured records and provenance back to the source object. Common validation checks the schema and the coverage, then publishes an immutable snapshot. Queries and workflows read snapshots. The proof of the abstraction is that a dataset from an uploaded CSV and one from a connector go through the same compiler, the same workers, the same result tables and the same lineage API.
What a snapshot promises
- A schema you reviewed, with a bounded sample, before publication.
- Stable record IDs, local to the snapshot and independent of display names or the source’s primary keys.
- Provenance per record: the row and header, the JSON pointer, or the source object and its evidence.
- Complete coverage, or an explicit count of omissions and errors published with the snapshot. A partial snapshot is never presented as complete.
- A version. Two identical rows remain two rows. There is no deduplication in this release; dedupe before import if you need it.
Files and app connections
Deduced is coming soon. Files are the simplest starting point: CSV, JSON, JSONL, TXT and Markdown. For app data, the product now includes a provider catalog and a guided connection and import flow. The integration directory shows the catalog we’re working from, including Pylon, Fireflies and Attio.
A listing is not a promise that every object, endpoint or account plan will work at launch. Authentication, permissions and what a provider exposes all matter. A useful import has to identify the records you need, fetch a sample, validate its shape, and make any incomplete coverage visible before you rely on it.
For example, support conversations can come from Pylon, meeting transcripts from Fireflies, and account context from Attio. Joining them requires a dependable shared identifier or a reviewed matching step. Similar display names alone are not enough.
Refresh is a new snapshot
A run pins the snapshot it read. Collecting fresh data creates a new input version; earlier runs retain theirs. That distinction matters when an external source changes or a collection is only partially complete. Compare runs with the source version and collection boundaries in view.
Binding a question to a source
A reusable question names the semantic slot it needs, such as content. A query binds tickets.messages or calls.transcript to that slot. The types have to match, and so does the meaning: a matching string type does not make a question written for articles the right question for a transcript. That review is yours; the compiler checks the shape.
What connectors do not promise
- An atomic snapshot of the remote system. Each adapter records what its platform actually supports.
- Stable pagination or complete search coverage. The collection specification and every page checkpoint are stored, so you can see what was fetched.
- Exact replay of a fetch. Refetching from a changing system is a new collection. Reprocessing captured evidence with a new parser is a new derived snapshot.
Next: explore the integration catalog or join the early-access waitlist and tell us which source you want to bring.